Real In, Real Out: What If We Only Use Real Data for Scene Text Editing?
NeurIPS, 2026
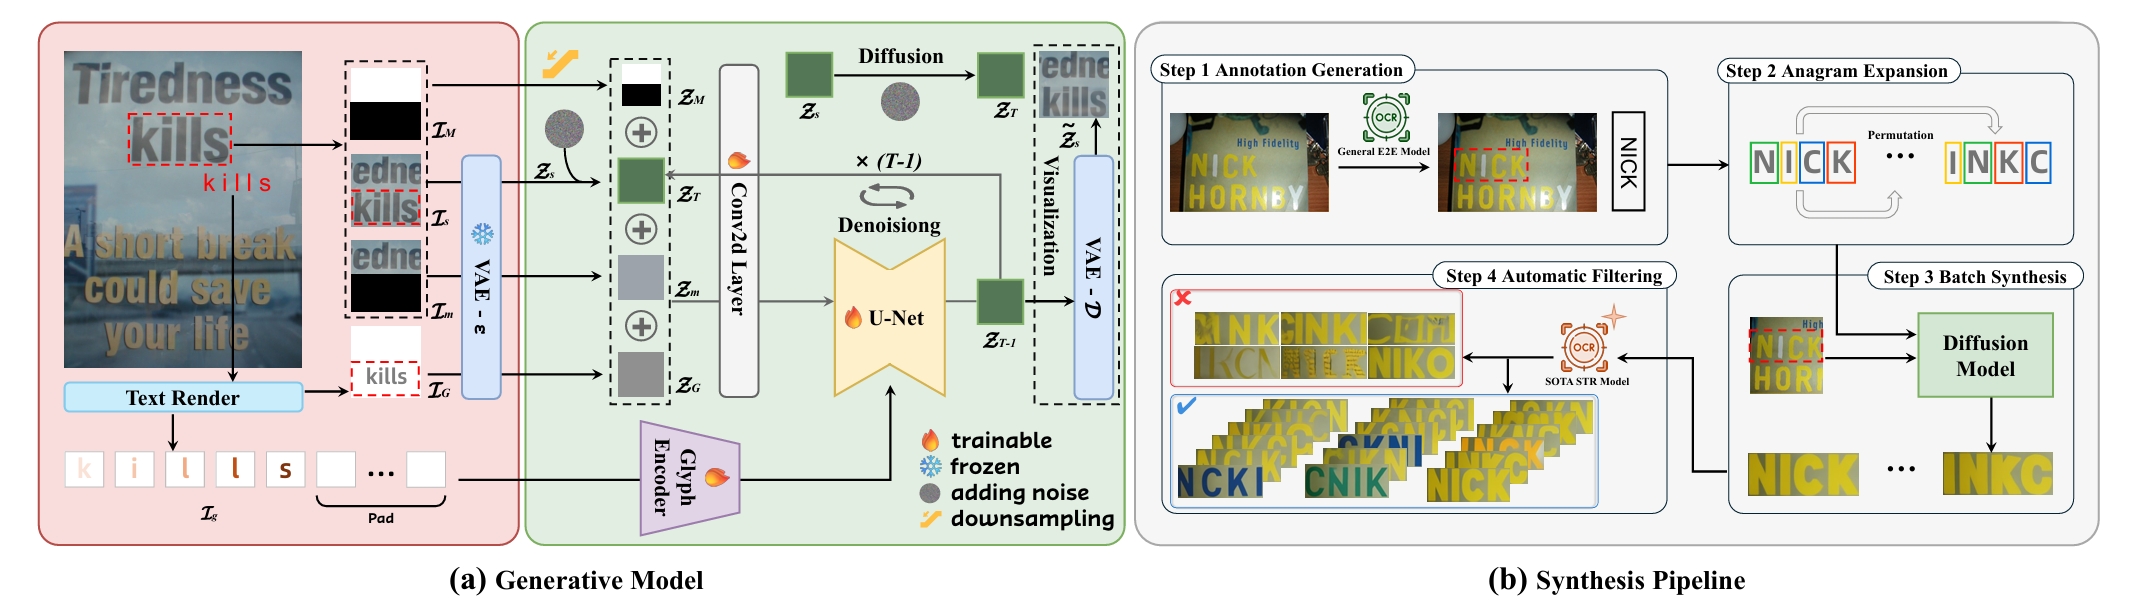
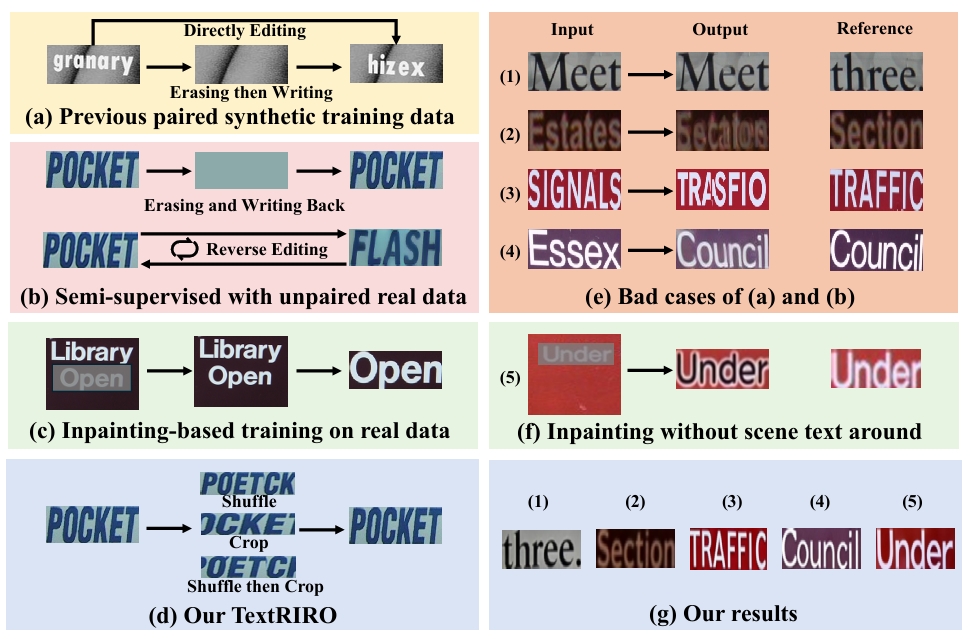
We challenge the common practice and investigate whether STE can be driven by turning each real sample into its own paired supervision. Concretely, we explore multiple ways to disrupt the original image (e.g., Crop, Shuffle, Mask) to construct self-paired training data, and build a strong baseline TextRIRO upon a conditional diffusion architecture. Our experiments show that combining character-column shuffling with image cropping (Shuffle&Crop) effectively destroys text semantics while preserving key style cues, enabling the model to learn editing behaviors directly from real text images. Furthermore, we leverage TextRIRO to build TextRIRO-3M, a large-scale realistic dataset for long-text recognition by concatenating edited and original images. Overall, TextRIRO lifts STE to realistic, reliable, and widely applicable new levels.